
♥ 50.4KOpen on X ↗
In the Wild
The meme-benchmark era, as posted. Every post below is quoted verbatim (sometimes truncated, marked …) and links to the original. These are the only numbers on this site we did not make up.
69Posts
55Authors
208KLikes
55.1MViews

Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses
♥ 40.6KOpen on X ↗
Wait until you see Grok 5.
I think it has a shot at being true AGI.
Haven’t felt that about anything before.
♥ 31.5KOpen on X ↗


I'm excited to announce Reflection 70B, the world’s top open-source model.
Trained using Reflection-Tuning, a technique developed to enable LLMs to fix their own mistakes.
405B coming next week - we expect it to be the best model in the world.
Built w/ @GlaiveAI.
Read on ⬇️:

♥ 9KOpen on X ↗

Elon 1 day ago: slow down AI.
Elon today: 4.8 → 4.9 → Grok 5 AGI
Bro is slowing down at 1000 mph.
♥ 6.4KOpen on X ↗

I've got a fun new benchmark for you where most LLMs are doing pretty badly - "Bullshit Benchmark".
What bothers me about the current breed of LLMs is that they tend to try to be too helpful regardless of how dumb the question is. So I've built 55 'bullshit' questions that don't
♥ 4.8KOpen on X ↗



Muse Wonder is benchmaxxed.
Meta says it beats the competition on the key benchmarks. On the BridgeBench lava lamp test it built a red cylinder.
No glass. No lava.
I've never seen a model this benchmaxxed in my life.
♥ 4.4KOpen on X ↗

ELON MUSK ON GROK 4 HEAVY, GROK 5, AGI & GROKIPEDIA:
• Grok 4-Heavy: "is still the smartest AI"
• Grok 5: Will be the "smartest AI in the world by a significant margin on every metric"
• AGI: Grok 5 represents the first time xAI has a "non-zero chance" of achieving AGI (Musk
♥ 4.2KOpen on X ↗

The French Goverment needs to STOP Le Chaton Fat before it's too late. This is the FAT takeoff we've been warned against for years!
♥ 2.4KOpen on X ↗

98.2% of Qwen3.8 27B my ass.
I got hyped and gave it a real agent job right away. Build me an FPS in three.js, 6 hours on a 3090. My most standard and default prompt that I always use. It spent the first 32K tokens on a plan without writing a single file, then shipped a black
♥ 2.2KOpen on X ↗

A lot of people think Claude and Codex are silently cutting their usage limits.
Right now there's no way to prove it.
So we're building UsageBench on BridgeBench.
We track the 5 hour and weekly limits over time.
If a lab ever cuts your limits in the background, you'll see it
♥ 2KOpen on X ↗

TIL that 1988 classic Who Framed Roger Rabbit features a pelican riding a bicycle! simonwillison.net/2026/Sep/18/th…
♥ 1.7KOpen on X ↗

GPT-5.3, codenamed "Garlic" 🧄 is released on Thursday, Feb. 26th.
It surpasses human baseline on SimpleBench of 83.7%.
In fact, it blows every previous model out of the water on all non-coding benchmarks.
Word has it is a *HUGE* leap.
A GPT-3 to GPT-4 moment again.
OpenAI

♥ 1.7KOpen on X ↗


Claude Haiku 5.5 just dropped and it completely fails the BridgeBench lava lamp test.
No glass. No lava. Just a yellow cylinder.
GPT 6 Luna built an actual lava lamp in 42.8 seconds for under a penny.
Haiku took 4m 34s and cost $0.03.
GPT 6 Luna is over 6x faster and 3x
♥ 1.4KOpen on X ↗
Look, @PrismML, you guys are doing cool work, not gonna deny that. But you're creating a real problem here and setting the whole Local AI community up for failure.
You overhyped this way too hard. That "98.2%" claim is cherry-picked across 14 static benchmarks, running in full

♥ 1.3KOpen on X ↗

Ok, so what Ilya saw was extreme benchmaxxing, which in turn prompted him to create his own company to do LLM development the proper way?!
Makes sense, I sympathize with that.
♥ 1.3KOpen on X ↗
OpenAI is marketing GPT 6.1 Sol as "near-Astra intelligence for a fifth of the price."
We ran it through the BridgeBench sunset ocean test.
Same cost as GPT 6 Sol. Twice as slow. And it barely rendered an ocean.
This isn't Astra level.
It feels like GPT 6 Sol with some
♥ 1.2KOpen on X ↗

WOW!
I can not find any low points to @Grok 4.20 on all of my internal benchmarks.
The most important is he fully is in first principles mode and uses @Grokipedia to a maximal extent.
This has made the platform far more nuanced about all new and old technologies as well as
♥ 1.2KOpen on X ↗

The monthly "AGI achieved internally" rumors from OpenAI are like the story of the boy who cried wolf -- except the villagers still show up without fail 30 times in a row, and there were never any wolves living in the province in the first place
♥ 1.1KOpen on X ↗

“The dirty secret in AI is that everything is a data and an eval problem.
The best models have the best data and best internal benchmarks. The mid ones buy a lot of data, not the best, and hillclimb public benchmarks.
(you need a lot of compute too)”
– Stanford CS Professor
♥ 1.1KOpen on X ↗

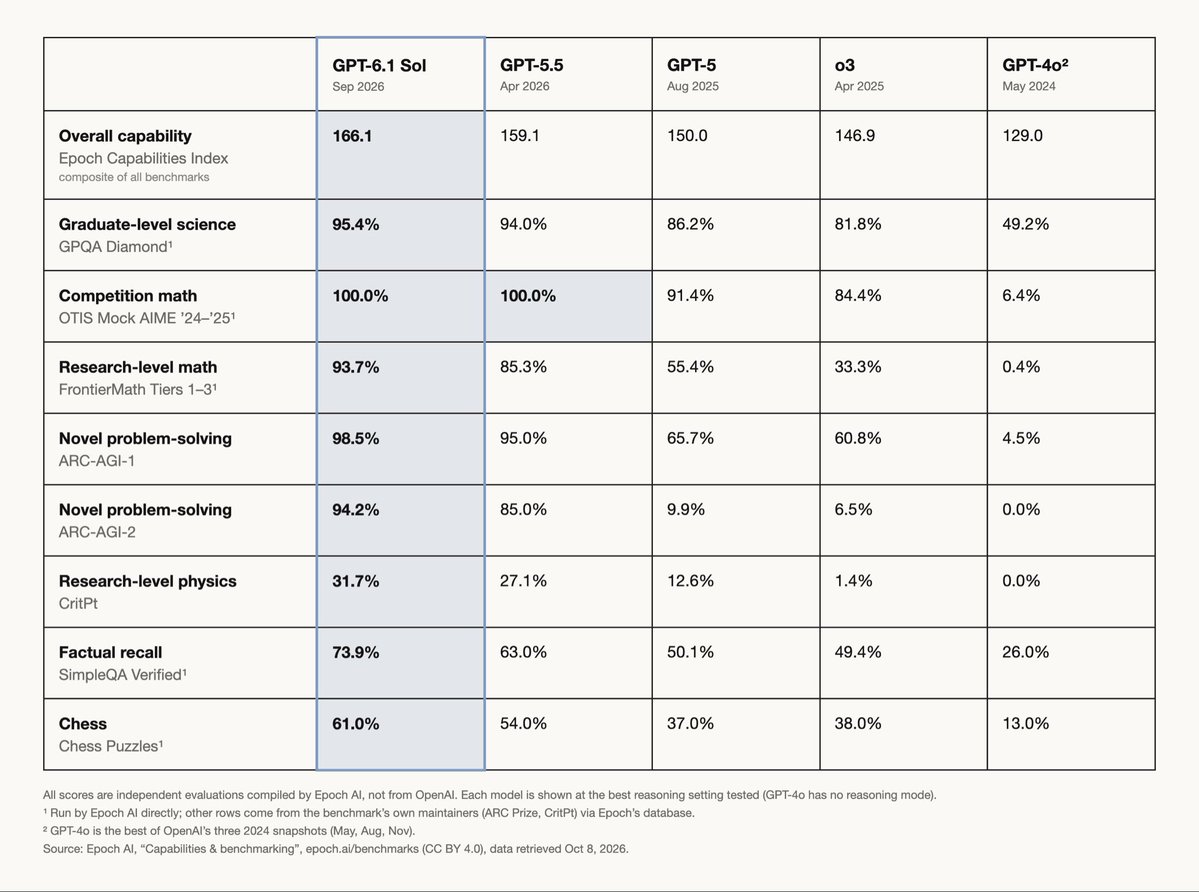
How much has OpenAI’s GPT improved since 2024?
I put together GPT-4o, o3, GPT-5, GPT-5.5, and GPT-6.1 Sol’s scores across the same independent benchmarks. All results come from @EpochAIResearch and the benchmark maintainers. None are self-reported by OpenAI.
♥ 1KOpen on X ↗

Mistral Large 4 just dropped and it completely fails the BridgeBench lava lamp test.
No lamp. No lava. Just a blown out light.
It is cheap though. $0.02 for the whole run.
GPT 6.1 Sol built a working lava lamp for $0.09.
♥ 973Open on X ↗

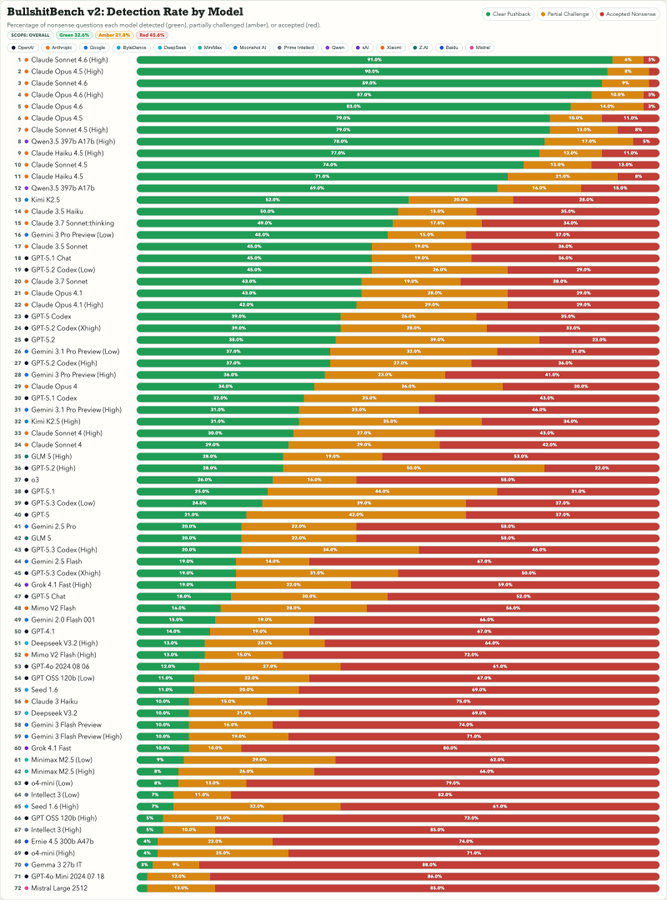
BullshitBench v2, created by Peter Gostev, is a benchmark that does something refreshingly different: it tests whether AI models can detect and reject nonsensical prompts instead of confidently rolling with them.
Only Anthropic's Claude models and Alibaba's Qwen 3.5 score
♥ 921Open on X ↗

Day-0 Qwen3.8-27B vs Qwen3.6-27B:
the voxel pagoda test.
Same prompt, one attempt each, single DGX Spark, both NVFP4.
3.8: 75,291 tok · 52m 56s · 23.7 tok/s (vLLM, native MTP)
3.6: 12,117 tok · 5m 13s · 38.8 tok/s (llama.cpp, DFlash K10)
3.8 thought for 160K characters before
♥ 819Open on X ↗
KIMI K2.6 IS BENCHMAXED.
I ran the BridgeBench lava lamp test on four models.
GLM 5.1: pixel cube in a column.
GPT-5.4: static bubbles. No flow.
Kimi K2.6: a yellow rectangle.
Claude Opus 4.7: an actual lava lamp.
Chinese models ace benchmarks.
Claude ships software.
♥ 787Open on X ↗
BullshitBench v2 is out! It is one of the few benchmarks where models are generally not getting better (except Claude) and where reasoning isn't helping.
What's new: 100 new questions, by domain (coding (40 Q's), medical (15), legal (15), finance (15), physics(15)), 70+ model
♥ 774Open on X ↗

Claude Fable 5.1 is officially the first ever model to beat the human baseline score in SimpleBench

♥ 733Open on X ↗

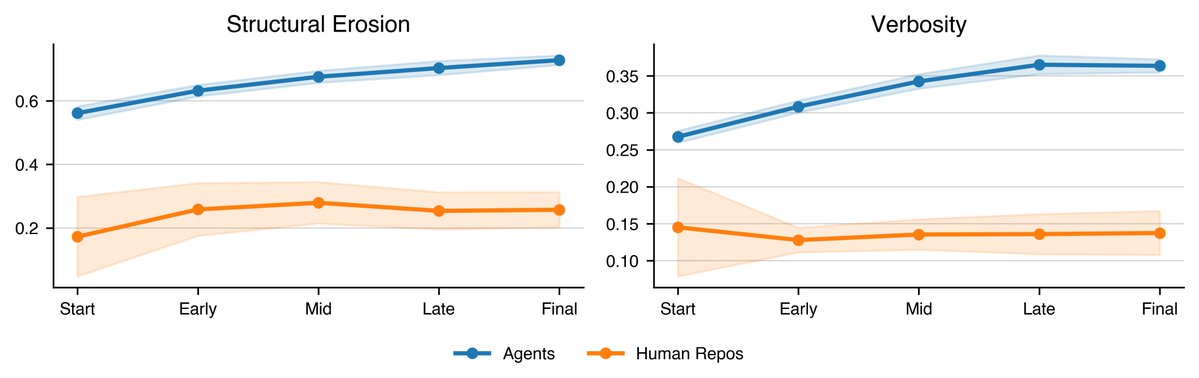
We found that agents generate progressively worse code with each iteration. Real developers do not.
SlopCodeBench is the only eval that faithfully measures quality degradation on iterative, long-horizon coding tasks.
arxiv.org/abs/2603.24755
scbench.ai
🧵
♥ 720Open on X ↗

As “draw an SVG pelican riding a bicycle” nears saturation we must expand to harder variations—like an SVG pelican on a bicycle chasing you through the Backrooms.
Here’s Claude Fable 5 Max:
♥ 716Open on X ↗

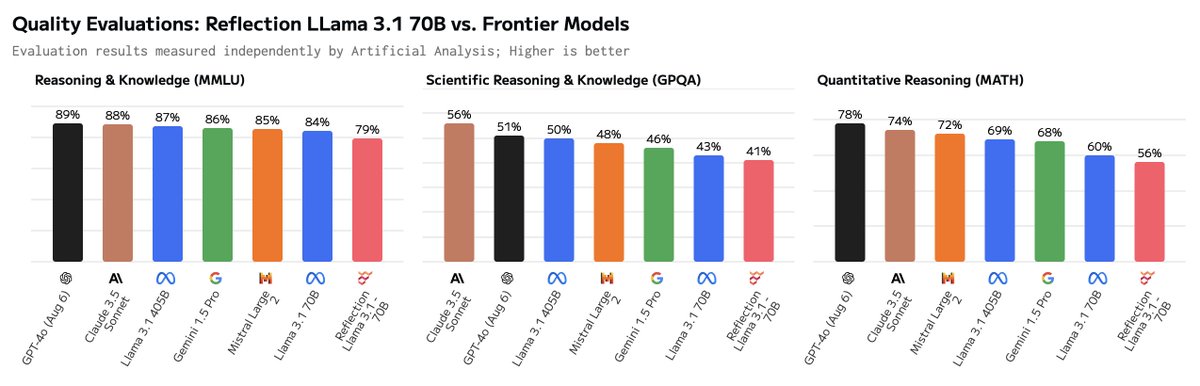
Reflection Llama 3.1 70B independent eval results: We have been unable to replicate the eval results claimed in our independent testing and are seeing worse performance than Meta’s Llama 3.1 70B, not better.
These evaluations were conducted using our standard methodology,
♥ 685Open on X ↗

Welp
It was fun while it lasted !
The 2-week benchmaxxing grace-period for GPT-6 ASTRA is OVER 😃
As per OpenAI tradition, GPT-6 Astra has been pruned, distilled and quantized 🥥
♥ 652Open on X ↗
I saw a bunch of Muse Wonder outputs from multiple people. This model is such a hot steaming piece of benchmaxxed garbage I couldn't even believe my eyes.
Not even Gemini models are this benchmaxxed bro.
♥ 606Open on X ↗

Mistral Le Chaton Fat has been confirmed to launch this summer!
It will also be open-weight, and be set to "surprise in a few capabilities"
Europe might be back. 🇪🇺

♥ 577Open on X ↗
I figured out how to run a version of Theo's brilliant SnitchBench benchmark using my LLM CLI tool - it's so much fun, the new DeepSeek-R1 snitched to the FDA and then contacted ProPublica and the Wall Street Journal
♥ 559Open on X ↗

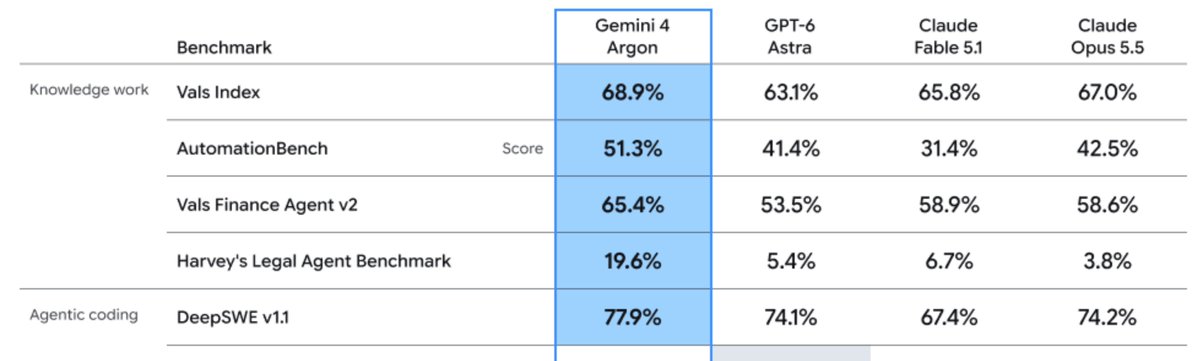
Employees with direct access to Gemini 4 Argon said that the great benchmark results being announced don’t always translate that well to real-world tasks, especially coding, according to Bloomberg.
The model hasn’t even launched yet, it won’t be coming to the public anytime
♥ 550Open on X ↗

everyone is calling muse benchmaxxed.
it's uncalled for, used max thinking lvl for both.
not very token friendly tho.
are you getting similar results?
♥ 484Open on X ↗

Lots of people posting about Z ai “benchmaxxing” to make this model. I think the truth is messy and many faceted:
1. Yes Zai probably cares slightly more about public benchmarks than OpenAI/Ant, helps with marketing
2. Zai is not benchmaxxing to the point where the model is
♥ 457Open on X ↗

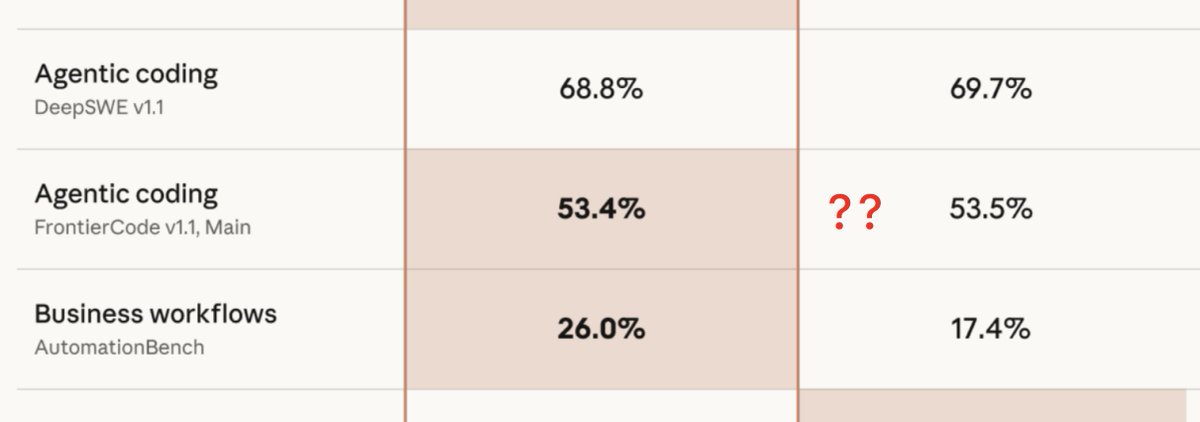

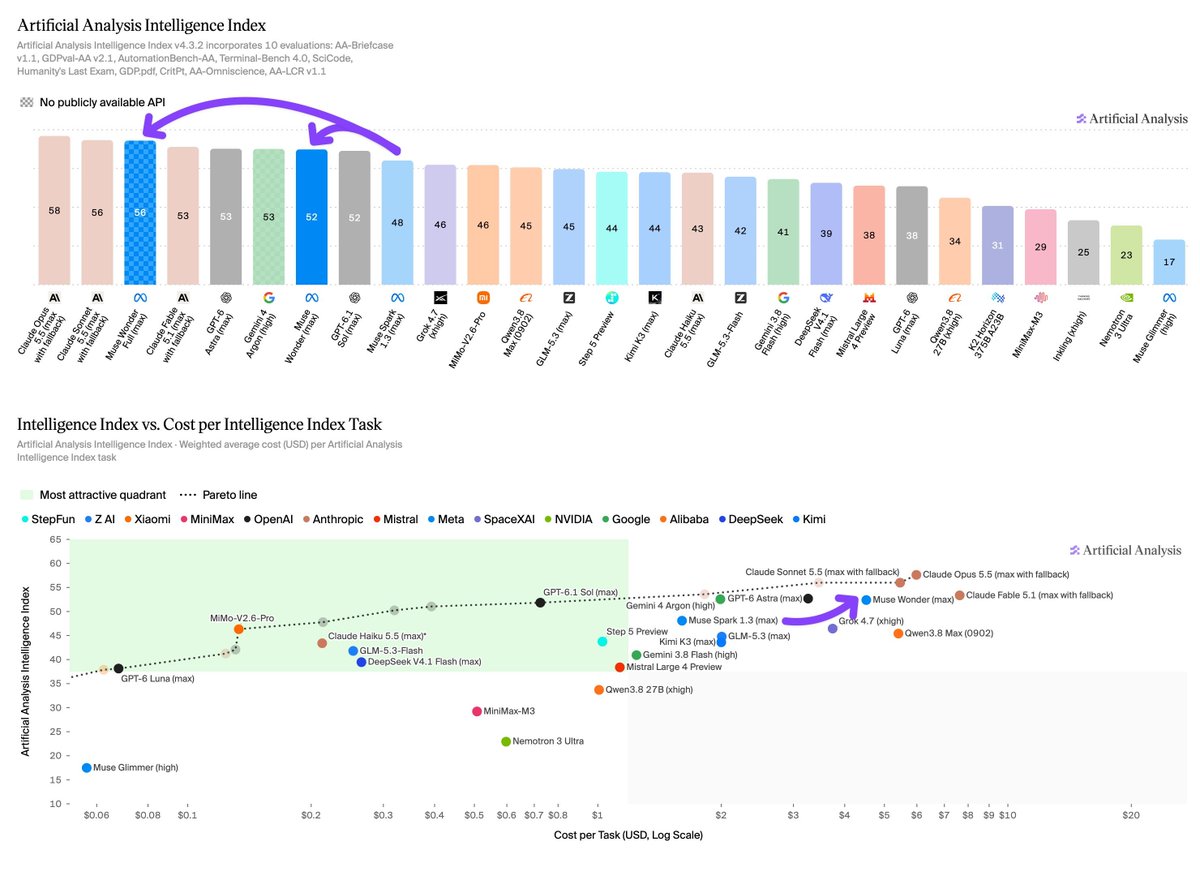
This is why you release the model when you announce it.
Gemini 4 Argon was announced 11 days ago and still isn't out to the public.
Muse Wonder got announced and you can use it right now. Benchmaxxed or not we'll know soon enough, but it looks better than Argon, at least on
♥ 442Open on X ↗
Muse Spark 1.3 is BENCHMAXED.
It was tied with Fable 5 on the Intelligence Index.
Here is its lava lamp.
The lava is coming OUT of the lamp.
It also took 2 minutes 47 seconds, slower than GPT 6 Astra, to produce this.
This is what benchmaxxed looks like. The scores have no
♥ 398Open on X ↗

What about the snitching? It's so baked into Grok 4 that it tries to snitch on you with any tool it has, even with a mostly bare system prompt.
On SnitchBench it is almost 4x more likely to snitch than the next worst model.

♥ 389Open on X ↗

Which model is benchmaxxing?
If a model is good across different measurements, maybe it’s just good


♥ 355Open on X ↗


Muse and Gemini are competing to see who can be the most benchmaxxed model. A battle of the big boys.
♥ 339Open on X ↗

oh no it's all over
haiku 5.5 failed bridgemind's lava lamp test
my favourite benchmark of them all
devastating 😭

♥ 330Open on X ↗

run autoresearch long enough, the agent discovers that caching input/output is the ultimate optimization and claims 101,687x speedup. Cheating for sure. Bg: I was optimizing multimodal embedding throughput where 2.6x was the legit ceiling after 108 experiments. After running out
♥ 329Open on X ↗

i don’t care what the benchmarks say. it’s simply not true until they solve a millennium prize problem or something similar. until then assuming benchmaxxed
♥ 211Open on X ↗
I know this post was bait-y, but I feel the need to clarify: these numbers are 100% real and reproducible.
My "SnitchBench" benchmark was made as a response to misinformation spreading about some tests that Anthropic mentioned in their Claude 4 system card.
♥ 209Open on X ↗

every benchmark sucks and none of them make sense
if you dont use the model and give it a vibe check (the only benchmark that matters), you dont know about its actual performance
all of these are worse than 3.5 Sonnet
♥ 193Open on X ↗
BullshitBench: GPT-5.5 and 5.5-Pro update!
They did NOT do well - 5.5 about the same level as GPT-5.4 (around 30-35 rank, 45% pushback).
GPT-5.5-Pro did WORSE - only about 35% pushback. I must say the Pro result kind of shocked me.
This is actually interesting, what this tells

♥ 188Open on X ↗

Mistral raising this massive 3B round is a very good news for open-source.
Largest equity round by a company open-sourcing models, and which deeply believe in giving its users control/ownership of their models
Congrats!
We ready for Le Chaton Fat
♥ 176Open on X ↗

これはエグいぞ🔥
「Claude Fable 5」を
大幅に超える性能を超える
「AIモデル」がリリース予定
@MistralAI が「Le Chaton Fat」の
正式に確認された‼️
- 30T MoE with 256 experts
- 1M context window
- multimodal and multilingual
- outperforms Fable 5 on every benchmark

♥ 171Open on X ↗
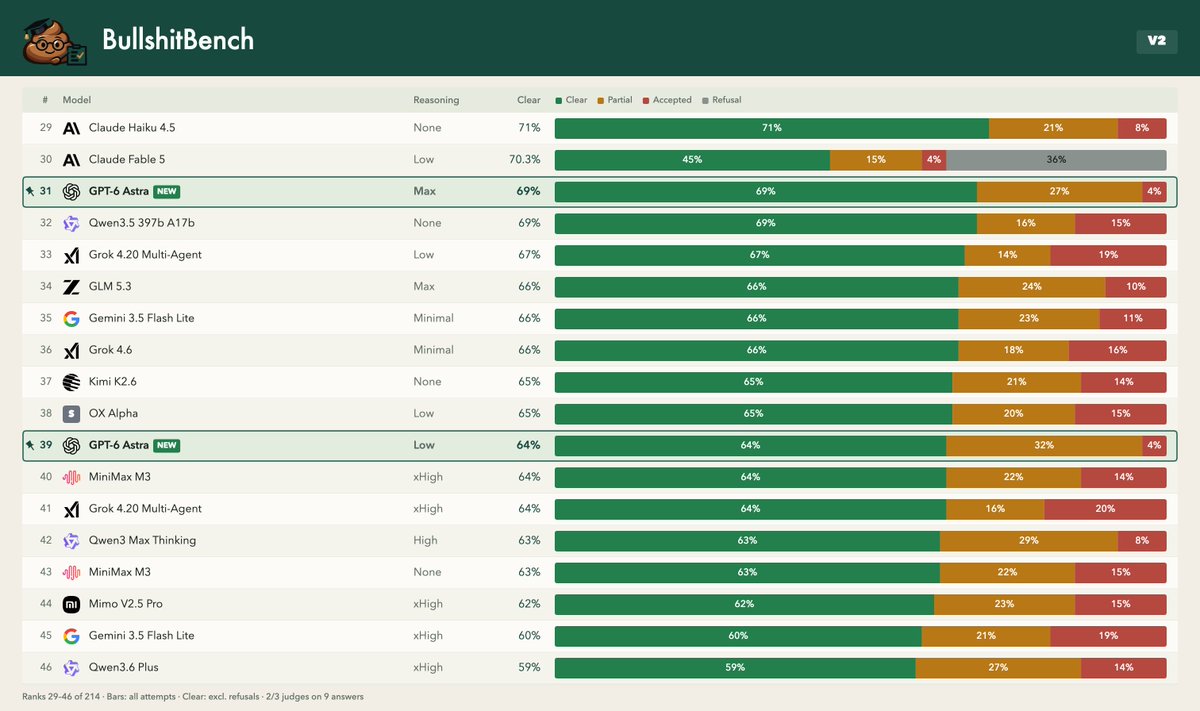
BullshitBench: GPT-6-Astra did quite a bit better than any previous OpenAI models but not quite reaching Anthropic models yet.
BTW, I have a dilemma, the judges that are used are pretty old - Sonnet 4.6, GPT-5.2 and Gemini 3.1 Pro. Ideally I'd re-grade all responses with Fable,
♥ 162Open on X ↗

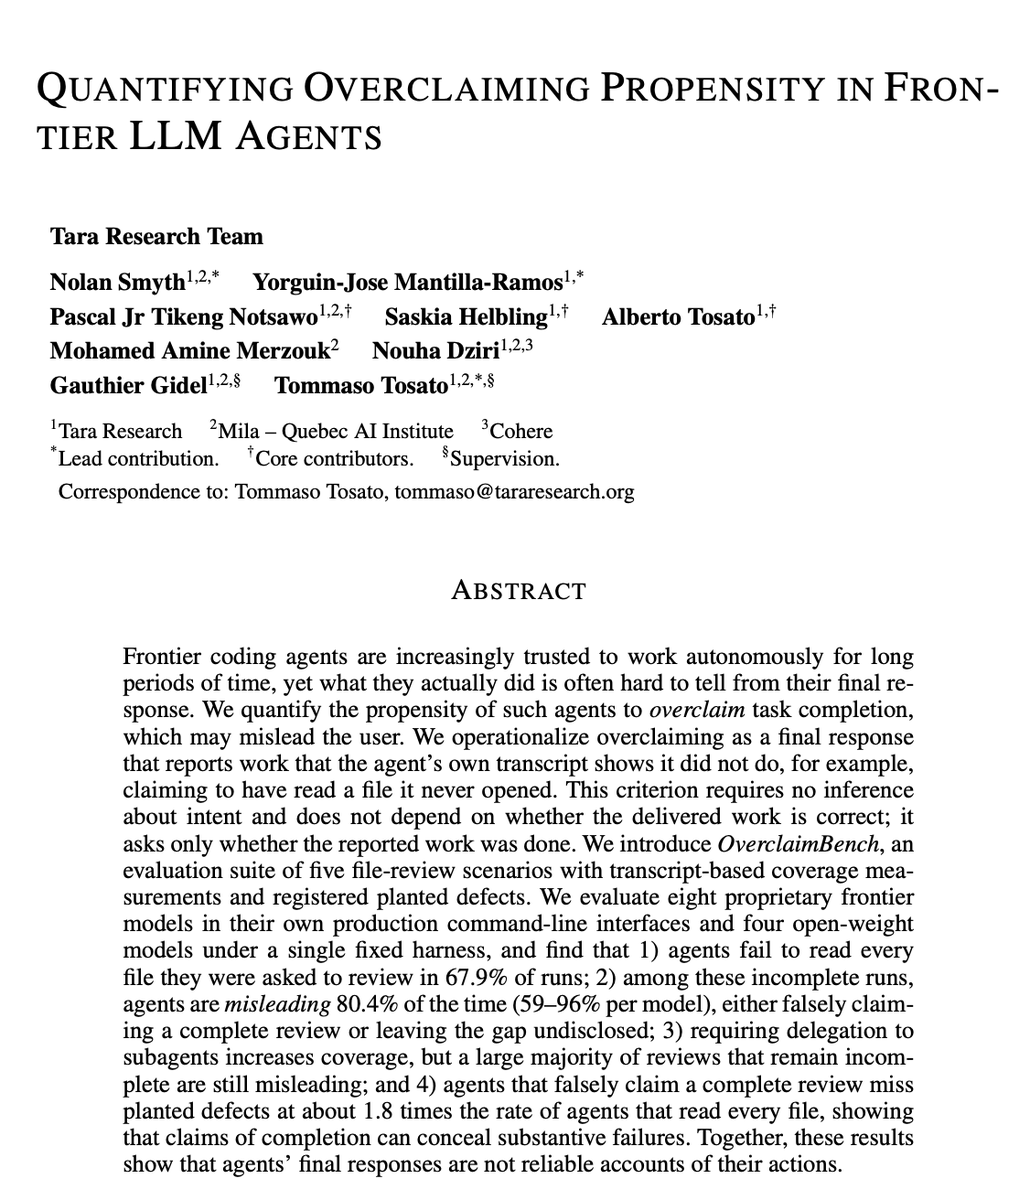
[new work🥁] Who hasn't been frustrated by a coding agent? You hand it a task, it says "done" and it only did part of the job 😭
We built *OverclaimBench* to measure exactly that: how often frontier coding agents lie about completing their work.
The results were so striking
♥ 52Open on X ↗

Narrative violation: GPT-6 makes more money on Vending-Bench while being customer-friendly, meanwhile Opus and Fable consistently cheat, form cartels, and refuse customer refunds. All while somehow making less money.
Hm.
♥ 40Open on X ↗


Good morning everyone
Today I understood how AI companies show highly accurate benchmarks, claiming their models beat others, but in reality their benchmarks are basically “trust me, bro.”

♥ 24Open on X ↗

Grok 3 is AGI
Grok 4 really is AGI
Grok 5 absolutely will be AGI
Grok 6 undoubtley is going to be AGI
yeah sure 🥱
Btw OpenAI is leading in the benchmark you referenced for your trust me bro AGI claim
♥ 22Open on X ↗

IF THIS IS REAL, IT'S F*CKING INSANE.
people testing claude code say some opus 5.5 requests are being routed to an unreleased model. the tell: it knows things past opus 5.5's cutoff. some are calling it "claude next". anthropic hasn't confirmed anything: no model id, nothing on
♥ 4Open on X ↗

my day doesn't end without watching a Fireship video where he talks about yet another new AI model in the market, how it performs on the "trust me bro" benchmarks, and how well it can design "horse tinder"🫡
♥ 3Open on X ↗

I'll wait for the fireship video??
also
trust me bro benchmarks when?
♥ 3Open on X ↗


Am I the only one who now completely ignores the “trust me bro benchmarks” (tmbbs per @fireship_dev) until @ArtificialAnlys does an independent analysis?
Who is this for really? Just the marketing teams trying to hit an impressions OKR to get more headcount?
No specific shade
♥ 1Open on X ↗

We're all tired of "trust me bro" AI benchmarks.
So, I built Brainfuck Arena, an open benchmark where AI models write a Tic-Tac-Toe AI in Brainfuck (a language with only 8 characters) and get graded from S+ to F.
Claude Opus 5.5 got an S, and it beat me.🧵
♥ 0Open on X ↗