The most benchmaxxed model ever released, independently confirmed to score well on benchmarks
Subject: Kimi K3.1 Pro
Claim
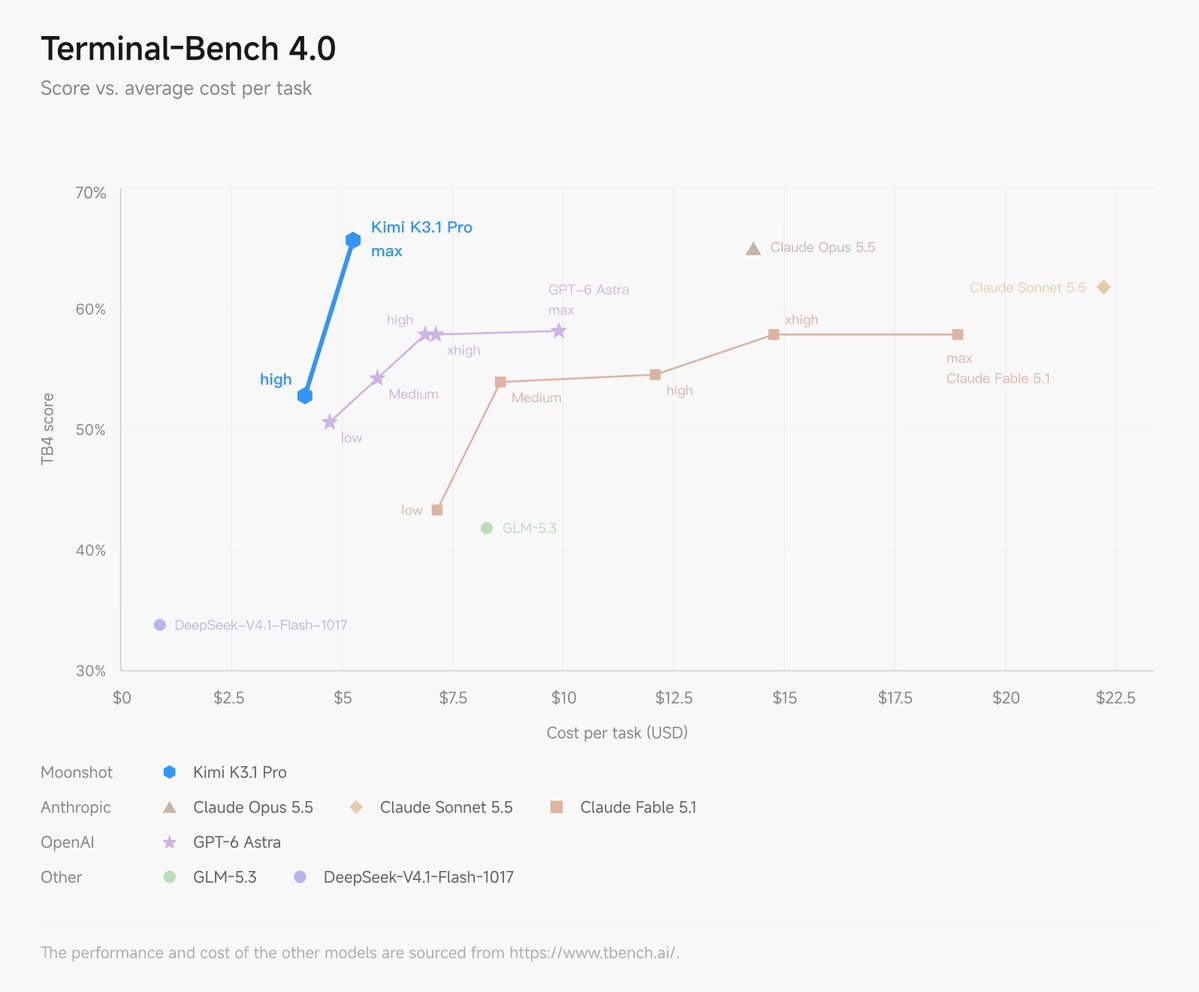
Moonshot's launch thread: 65.7% on Terminal-Bench 4.0, "ahead of GPT-6 Astra"; "SOTA on OfficeQA Pro v2"; and, "on internal benchmarks", "~4.2× K3 on simulated business operation". Fan summary: it "beats every listed US frontier model on 6 of 14 benchmarks in Moonshot's evaluations".
Finding
Sixty-six minutes after release it was declared "the most benchmaxxed model ever released". Hands-on reports followed: worse than Sonnet 5.5 for one user, beaten by DeepSeek V4.1 Flash at 49 times the price in one test, eleventh on a human-preference arena, 21% on BiGym 2. The complication: Artificial Analysis independently measured 67% on Terminal-Bench 4.0, above Moonshot's own 65.7% and the highest of any model, and an index of 55, fourth of 215. The suspicious part is the shape. Terminal-Bench 4.0 rose from 13% to 67% in one version; Humanity's Last Exam rose five points. That is either a breakthrough in agents or a breakthrough in Terminal-Bench, and we are not qualified to say which. Judging by the replies, neither is anyone else.
Timeline
- 23 Oct 2026Self-reported: "ahead of GPT-6 Astra" on Terminal-Bench 4.0.@Kimi_Moonshot · ♥ 2.1K ↗
- 23 Oct 2026"On internal benchmarks … ~4.2× K3 on simulated business operation."@Kimi_Moonshot · ♥ 770 ↗
- 23 Oct 2026Independent: 67% on Terminal-Bench 4.0, up from 13% for Kimi K3, the highest of any model.@ArtificialAnlys · ♥ 260 ↗
- 23 Oct 2026"The most benchmaxxed model ever released."@The_Alex · ♥ 914 ↗
- 23 Oct 2026"Even Sonnet 5.5 gives me better results."@pankajkumar_dev · ♥ 112 ↗
- 24 Oct 2026Eleventh on Agent Arena, "below even Opus 5 and Fable 5".@thegenioo · ♥ 147 ↗
- 25 Oct 2026"Couldn't even beat DeepSeek V4.1 Flash on xhigh. At 49x the price."@EnvolDev · ♥ 166 ↗
- 25 Oct 202621% on BiGym 2.@Nag1ovo · ♥ 48 ↗
- 26 Oct 2026"Paid 29x more for the worse one."@semichenkko · ♥ 17 ↗