R
Reflection 405B
PromisedReflectionReasoning
Announced 5 Sept 2024, not released. Announced alongside Reflection 70B as "coming next week". We are still in that week.
Trust Me Bro Intelligence Indexn/aCannot be used, so cannot be measured
Self-reported"Best model in the world"The number in the launch post
Benchmaxx Gap+∞Self-reported minus measured
Output speed—Tokens per second
Cost per task—USD, TMB Index task average
Context window128kRemembers 0k of it
Days to ship769+Still counting
Evaluations
How Reflection 405B scores on every benchmark
This model cannot be used, so values below are derived from public claims rather than measurement. Bars show where the score sits between the worst and best model on each benchmark. Rank 1 is best, whatever "best" means for that benchmark.
Incident database
Filed incidents
In the wild
What people posted
Real posts, quoted verbatim. The scores on this page are not real; these are.

I'm excited to announce Reflection 70B, the world’s top open-source model.
Trained using Reflection-Tuning, a technique developed to enable LLMs to fix their own mistakes.
405B coming next week - we expect it to be the best model in the world.
Built w/ @GlaiveAI.
Read on ⬇️:

♥ 9KOpen on X ↗

Reflection Llama 3.1 70B independent eval results: We have been unable to replicate the eval results claimed in our independent testing and are seeing worse performance than Meta’s Llama 3.1 70B, not better.
These evaluations were conducted using our standard methodology,
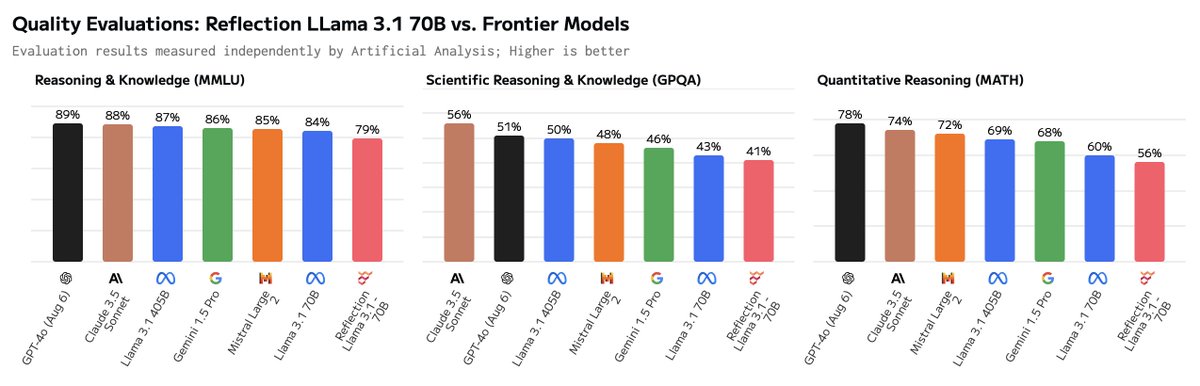
♥ 685Open on X ↗
Compare