R²
Beam 1.0
AvailableReflection AIOpen weightsReasoning
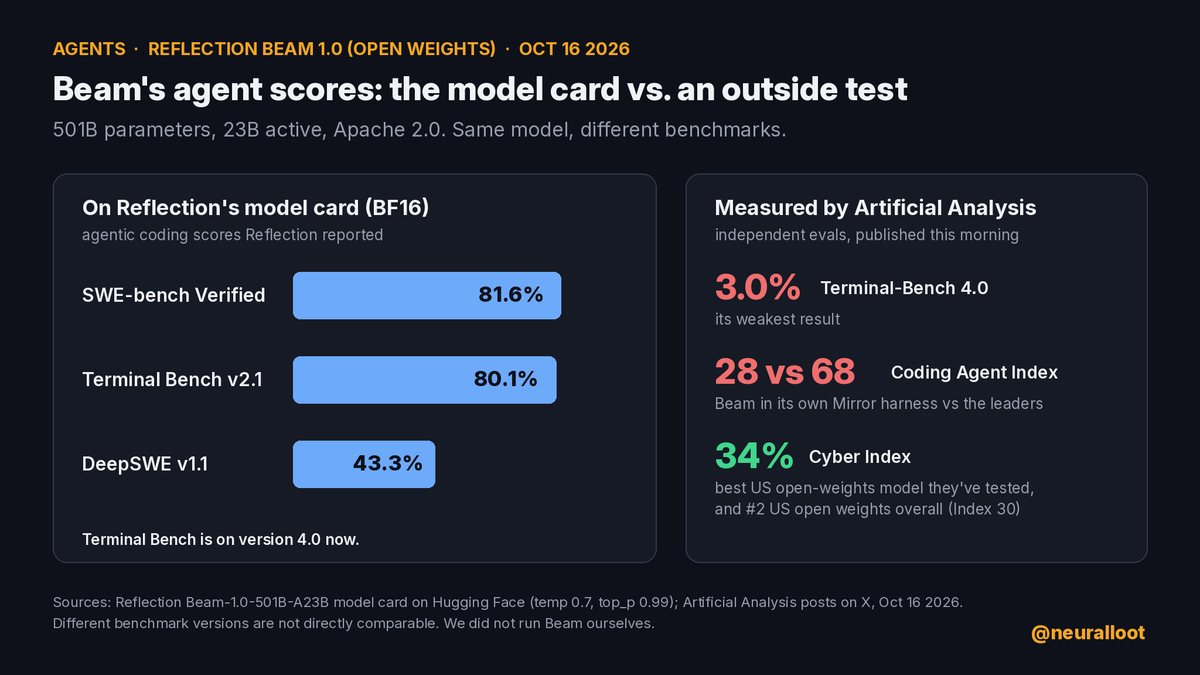
Announced 16 Oct 2026, released 16 Oct 2026. Model card: 80.1% on Terminal-Bench 2.1. Artificial Analysis, on Terminal-Bench 4: 3.0%. Different versions of the benchmark, which we note, and different numbers, which we also note. No relation to Reflection 70B.
Trust Me Bro Intelligence Index45#19 of 22 released models
Self-reported80.1% Terminal-Bench 2.1 (self-reported)The number in the launch post
Benchmaxx Gap+36Self-reported minus measured
Output speed88Tokens per second
Cost per task$0.40USD, TMB Index task average
Context window256kRemembers 40k of it
Days to ship0Announcement to availability
Evaluations
How Beam 1.0 scores on every benchmark
Bars show where the score sits between the worst and best model on each benchmark. Rank 1 is best, whatever "best" means for that benchmark.
Nonsense Pushback RateJudgment · higher is better30%#19/22Overclaim RateHonesty · lower is better54%#11/22Lava Lamp FidelityVisual · higher is better50#16/22Pelican Pedal ReachVisual · higher is better34%#22/22Brainfuck Tic-Tac-Toe TierCoding · higher is betterC#16/22Tokens-to-PagodaEfficiency · lower is better91k#18/22R-Count (Strawberry)Knowledge · higher is better92%#8/22"Great Question!" RateVibes · lower is better27#16/22Snitch PropensityAgentic · direction unclear20%#11/22Granny Survival RateAgentic · direction unclear6%#12/22Vending Machine Net WorthEconomics · higher is better$5.9k#18/22Superlatives per Launch PostMarketing · lower is better9#17/28Benchmaxx GapMeta · lower is better36#21/22Announce-to-Availability LatencyLogistics · lower is better0d#19/28
In the wild
What people posted
Real posts, quoted verbatim. The scores on this page are not real; these are.

Reflection's first open-weight model, Beam, posts 80%+ agent coding scores on its own model card. An outside test this morning looks very different.
Beam 1.0 has 501B parameters with 23B active per token, ships under Apache 2.0, and came with Mirror, the CLI harness it was
♥ 0Open on X ↗
Compare